ruby_llm-providers-lms
A RubyLLM provider for LM Studio: run local models through the same Ruby API you use for hosted ones.
No API key and no configuration: start LM Studio's server (lms server start)
and the :lms provider talks to http://localhost:1234/v1.
What it covers
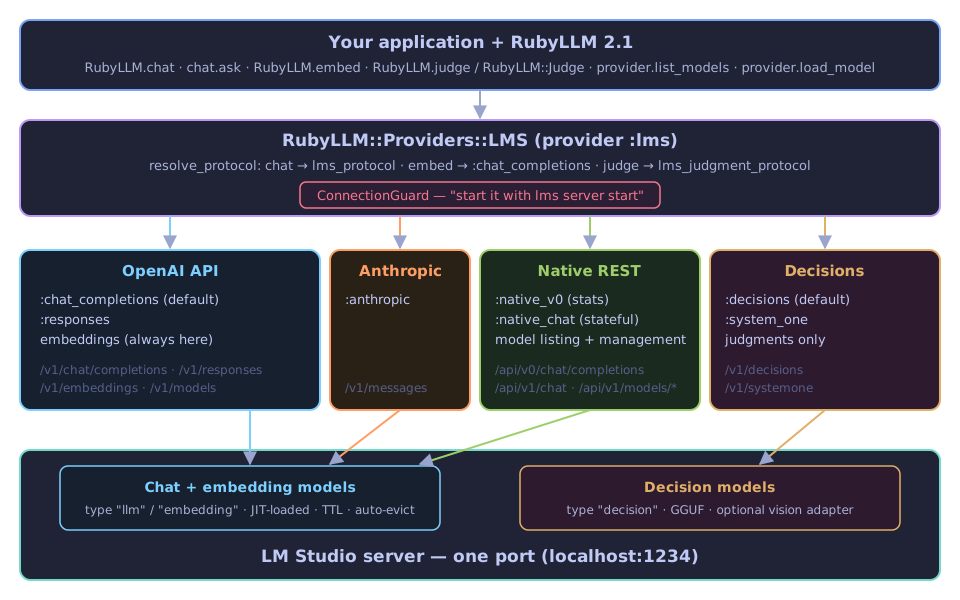
LM Studio serves several APIs on one port, and this gem speaks all of them:
| API | What you get | Protocols |
|---|---|---|
| OpenAI | Chat, streaming, tools, structured output, vision, reasoning, embeddings | :chat_completions (default), :responses |
| Anthropic | Claude-style Messages API against a local model | :anthropic |
| Native REST | Inference stats, server-stored conversations, MCP integrations, model management | :native_v0, :native_chat |
| Decisions | Typed judgments from decision models: probabilities, choices and scores in milliseconds | :decisions (default), :system_one |
New in 0.3: judgments with decision models
LM Studio 0.4.26 added endpoints for decision models: models that answer typed questions with probabilities instead of writing text. RubyLLM 2.1 calls these judgments, and this gem points them at LM Studio:
class TicketTriage < RubyLLM::Judge
  model 'd1-omni-600m', provider: :lms

  probability :urgent, 'Does this need attention today?'
  choice :team, 'Which team should handle this?' do
    billing   'Charges and refunds'
    technical 'Bugs and outages'
  end
  score :frustration, 'How frustrated is the customer?', %w[Calm Annoyed Angry]
end

judgment = TicketTriage.judge('You charged my card twice. Refund it today.')
judgment.urgent.probability  # => 0.97
judgment.team.choice         # => :billing
Open-source decision models such as D1 Omni 600M answer in tens of milliseconds on a laptop. See Judgments.
The one thing to know first
What a call does depends on two choices, not one
LM Studio runs whatever model you downloaded behind every protocol. The
protocol decides what is expressible — with_schema is honored on
:chat_completions and silently ignored on :responses. The model
decides whether it honors what the protocol accepted — qwen3 obeys
tool_choice: "required", gpt-oss ignores it. Test against the models you
intend to ship on. Choosing a protocol maps the first
axis.
Requirements
- Ruby 3.3 or newer
- RubyLLM 2.1.1 or newer
- LM Studio with its server running (0.4.26 or newer for judgments)